Tuesday, 14 July 2020

SNMP Trap


The SNMP (Simple Network Management Protocol) allows network management to communicate with different network components. Because of this, it is important for all network hardware to be equipped with an SNMP agent that allows for it to be communicated back to network management. Once the network is connected, the elements are able to send messages back to network management, and at the same time, network management can send messages to the elements for information. It is this constant back and forth between the network and all its elements that necessitates an SNMP.


What is an SNMP Trap?


An SNMP trap allows an element, such as a printer or scanner, to contact network management when there is a significant event. This is done via unsolicited SNMP messages. For example, if the printer is out of paper and an individual is trying to print, an SNMP trap will be sent to the computer with the message, “Out of paper, add more.” Or, if there is a power failure on one of the network elements, the SNMP Trap will let the network manager know so that he can take the necessary steps to correct the problem.

For the most part, an SNMP Trap is unnecessary when dealing with a single personal computer because one person can easily manage this. SNMP becomes important and helpful, though, when a network manager is dealing with numerous network elements that all have numerous elements themselves. This makes it very difficult to manually manage all of them. The SNMP Trap allows the manager to be notified when there is a problem so he can respond to it quickly without having to manually check everything to see what the error is.

For management to determine what is going on with the element that sent the trap, it needs to have a management information base (MIB) installed. What this does is allow the manager to determine which element is having problems. This provides the OID and any information that goes along with it so the manager can make an informed decision on what corrective measures to take.


What are the Definitions of an SNMP Trap?


There are a series of SNMP Trap definitions for RFC 1157. These are:

    Enterprise: Identifies which object sent the trap.
    Agent address: Gives the object’s address.
    Generic Trap Type: Provides generic types of traps.
    Specific Trap Code: Provides specific codes for traps.
    Time stamp: Gives the time between the last reinitialization and the trap generation.

Wednesday, 8 July 2020

Data Mining


Data mining is usually defined as searching, analyzing and sifting through large amounts of data to find relationships, patterns, or any significant statistical correlations. With the advent of computers, large databases and the internet, it is easier than ever to collect millions, billions and even trillions of pieces of data that can then be systematically analyzed to help look for relationships and to seek solutions to difficult problems. Besides governmental uses, many marketers use data mining to find strong consumer patterns and relationships. Large organizations and educational institutions also data mine to find significant correlations that can enhance our society.

While data mining is amoral in the fact that it only looks for strong statistical correlations or relationships, it can be used for either good or not so good purposes. For instance, many government organizations depend on data mining to help them create solutions for many societal problems. Marketers use data mining to help them pin point and focus their attention on certain segments of the market to sell to, and in some cases black hat hackers can use data mining to steal and scam thousands of people.

How does data mining work? Well the quick answer is that large amounts of data are collected. Usually most entities that perform data mining are large corporations and government agencies. They have been collecting data for decades and they have lots of data to sift through. If you are a fairly new business or individual, you can purchase certain types of data in order to mine for your own purposes. In addition, data can also be stolen from large depositories by hackers by hacking their way into a large database or simply stealing laptops that are ill protected.

If you are interested in a small case study on how data mining is collected, used and profited off of, you can look at your local supermarket. Your supermarket is usually an extremely lean and organized entity that relies on data mining to make sure that it is profitable. Usually your supermarket employs a POS (Point Of Sale) system that collects data from each item that is purchased. The POS system collects data on the item brand name, category, size, time and date of the purchase and at what price the item was purchased at. In addition, the supermarket usually has a customer rewards program, which also is input into the POS system. This information can directly link the products purchased with an individual. All this data for every purchase made for years and years is stored in a database in a computer by the supermarket.

Now that you have a database with millions upon millions of data fields and records what are you going to do with it? Well, you data mine it. Knowledge is power and with so much data you can uncover trends, statistical correlations, relationships and patterns that can help your business become more efficient, effective and streamlined.

The supermarket can now figure out which brands sell the most, what time of the day, week, month or year is the most busiest, what products do consumers buy with certain items. For instance, if a person buys white bread, what other item would they be inclined to buy? Typically we can find its peanut butter and jelly. There is so much good information that a supermarket can use just by data mining their own data that they have collected.

Wednesday, 1 July 2020

ODBC (Open Database Connectivity)


ODBC (Open Data Base Connectivity) is an interface to access databases via SQL queries. ODBC can be used as an access tool to various databases such as MS-Access, dBase, DB2, Excel, and Text. Through these Call Level Interface (CLI) specifications of the SQL Access Group, the OBDC allows a neutral way of accessing the data stored in personal computers and various databases. It was first created by Microsoft and Simba Technologies. ODBC 1.0 was initially released in September 1992, and eventually became a part of the international SQL standard in 1995. Microsoft originally shipped the ODBCs as a set of DLLs and still today, ships the set with every copy of Microsoft Windows. Today, more and more operating systems such as Unix and Apple are adopting the ODBC.

The strength of ODBC is that by providing a universal data access interface, it allows independent software companies and parties to not have to learn multiple application programming interfaces. To simply put, with ODBC, applications can simultaneously access, view, and modify database from numerous and quite diverse databases. This is because the ODBC “re-codes” the SQL queries so that it would be readable by the various different databases.
However, the ODBC also has its drawbacks. As managing a huge number of ODBC clients can mean an immense amount of drivers and DLLs being run, this could lead to a system administration overhead. Nonetheless, this minor issue led to further uses of the ODBC server technology (or the “Multi-Tier ODBC Drivers”) to alleviate the load. Also, as drivers are a key in ODBCs, some have raised the issue of the newer drivers’ stability, as often many have shown to have bugs in them.

How ODBC is Processed

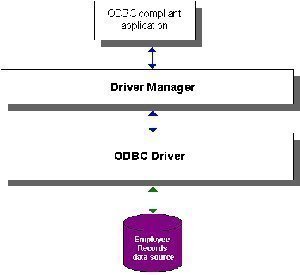
To use the ODBC, three components are needed: ODBC client, ODBC driver, and a DBMS server (ex. Microsoft Access, SQL Server, Oracle, and FoxPro). Firstly, the ODBC client will use a command (referred to as “ODBC”) to interact (requesting and/or sending data) with the DBMS server (back-end). However, the DBMS server will not understand the command by the ODBC client yet, as the command has yet to be processed through the ODBC driver (front-end). So then, the ODBC driver will decode the command that can be processed by the ODBC server and be sent there. The ODBC server will then respond back to the ODBC driver which will translate the final output to the ODBC client.

ODBC Drivers

ODBC drivers are specific to each type of database.

Where to Get an Oracle ODBC Driver

The Oracle ODBC Drivers Download Page is the source for official Oracle ODBC drivers.
The Easysoft ODBC Oracle Driver improves on the stock Oracle ODBC drivers by providing improved performance and easier maintenance.
OpenLink Software provides both Single-Tier and Multi-Tier Oracle ODBC drivers.
Attunity provides a data adapter which includes an Oracle ODBC driver.

Where to Get a MySQL ODBC Driver

MySQL Connector/ODBC is the official MySQL ODBC driver.
OpenLink Software provides both Single-Tier and Multi-Tier MySQL ODBC drivers.

Sources for Other ODBC Drivers

To search for an ODBC driver for another database, check the unixODBC list of ODBC drivers which work with unixODBC.


ODBC Driver Managers

The two main ODBC driver managers for Unix are iODBC and unixODBC.
where to get an ODBC driver manager
iODBC (Independent Open DataBase Connectivity) is an Open Source platform independent implementation of both the ODBC and X/Open specifications. iODBC provides both an ODBC driver manager and an SDK that facilitates the development of database-independent applications. iODBC includes a GTK+-based administration tool.
iODBC has been ported to numerous platforms, including: Linux (x86, Itanium, Alpha, Mips, and StrongArm), Solaris (Sparc & x86), AIX, HP-UX (PA-RISC & Itanium), Digital UNIX, Dynix, Generic Unix 5.4, FreeBSD, MacOS 9, MacOS X, DG-UX, and OpenVMS.
unixODBC provides Unix applications with the same ODBC 3.51 API and facilities available under Windows. unixODBC provides a Driver Manager that supports the full ODBC API and performs the ODBC 3 to ODBC 2 translations with UNICODE to ANSI conversion. unixODBC also includes a set of graphical utilities that allow users to specify connections to DBMSes to be used by applications, a collection of ODBC drivers including a simple text based driver, an NNTP driver, a Postgres driver and others, and a selection of templates and libraries that to aid in the construction of ODBC drivers. unixODBC works with MySQL, Postgres, StarOffice/OpenOffice, Applixware, iHTML, PHP, Perl DBD::ODBC, and many other applications and drivers. Connection pooling is also provided to increase performance with applications such as PHP. unixODBC includes a QT-based administration GUI.

Thursday, 25 June 2020

Data Dictionary


A data dictionary is an integral part of a database. It holds information about the database and the data that it stores, i.e., the meta-data. Any well designed database will surely include a data dictionary as it gives database administrators and other users easy access to the type of data that they should expect to see in every table, row, and column of the database, without actually accessing the database.
Since a database is meant to be built and used by multiple users, making sure that everyone is aware of the types of data each field will accept becomes a challenge, especially when there is a lack of consistency when assigning data types to fields. A data dictionary is a simple yet effective add-on to ensure data consistency.
Some of the typical components of a data dictionary entry are:
•    Name of the table
•    Name of the fields in each table
•    Data type of the field (integer, date, text…)
•    Brief description of the expected data for each field
•    Length of the field
•    Default value for that field
•    Is the field Nullable or Not Nullable?
•    Constraints that apply to each field, if any
Not all of these fields (and many others) will apply to every single entry in the data dictionary. For example, if the entry were about the root description of the table, it might not require any information regarding fields. Some data dictionaries also include location details, such as each field’s current location, where it actually came from, and details of the physical location such as the IP address or DNS of the server.


Format and Storage

There exists no standard format for creating a data dictionary. Meta-data differs from table to table. Some database administrators prefer to create simple text files, while others use diagrams and flow charts to display all their information. The only prerequisite for a data dictionary is that it should be easily searchable.
Again, the only applicable rule for data dictionary storage is that it should be at a convenient location that is easily accessible to all database users. The types of files used to store data dictionaries range from text files, xml files, spreadsheets, an additional table in the database itself, to handwritten notes. It is the database administrator’s duty to make sure that this document is always up to date, accurate, and easily accessible.

Creating the Data Dictionary

First, all the information required to create the data dictionary must be identified and recorded in the design documents. If the design documents are in a compatible format, it should be possible to directly export the data in them to the desired format for the data dictionary. For example, applications like Microsoft Visio allow database creation directly from the design structure and would make creation of the data dictionary simpler. Even without the use of such tools, scripts can be deployed to export data from the database to the document. There is always the option of manually creating these documents as well.

Advantages of a Data Dictionary

The primary advantage of creating an informative and well designed data dictionary is that it exudes clarity on the rest of the database documentation. Also, when a new user is introduced to the system or a new administrator takes over the system, identifying table structures and types becomes simpler.  In scenarios involving large databases where it is impossible for an administrator to completely remember specific bits of information about thousands of fields, a data dictionary becomes a crucial necessity.

Monday, 15 June 2020

Multimedia Database


A multimedia database is a database that hosts one or more primary media file types such as .txt (documents), .jpg (images), .swf (videos), .mp3 (audio), etc. And loosely fall into three main categories:
  • Static media (time-independent, i.e. images and handwriting)
  • Dynamic media (time-dependent, i.e. video and sound bytes)
  • Dimensional media (i.e. 3D games or computer-aided drafting programs- CAD)
All primary media files are stored in binary strings of zeros and ones, and are encoded according to file type.
The term "data" is typically referenced from the computer point of view, whereas the term "multimedia" is referenced from the user point of view.


Types of Multimedia Databases


There are numerous different types of multimedia databases, including:
  • The Authentication Multimedia Database (also known as a Verification Multimedia Database, i.e. retina scanning), is a 1:1 data comparison
  • The Identification Multimedia Database is a data comparison of one-to-many (i.e. passwords and personal identification numbers
  • A newly-emerging type of multimedia database, is the Biometrics Multimedia Database; which specializes in automatic human verification based on the algorithms of their behavioral or physiological profile.
This method of identification is superior to traditional multimedia database methods requiring the typical input of personal identification numbers and passwords-
Due to the fact that the person being identified does not need to be physically present, where the identification check is taking place.
This removes the need for the person being scanned to remember a PIN or password. Fingerprint identification technology is also based on this type of multimedia database.


Difficulties Involved with Multimedia Databases


The difficulty of making these different types of multimedia databases readily accessible to humans is:
  • The tremendous amount of bandwidth they consume;
  • Creating Globally-accepted data-handling platforms, such as Joomla, and the special considerations that these new multimedia database structures require.
  • Creating a Globally-accepted operating system, including applicable storage and resource management programs need to accommodate the vast Global multimedia information hunger.
  • Multimedia databases need to take into accommodate various human interfaces to handle 3D-interactive objects, in an logically-perceived manner (i.e. SecondLife.com).
  • Accommodating the vast resources required to utilize artificial intelligence to it's fullest potential- including computer sight and sound analysis methods.
  • The historic relational databases (i.e the Binary Large Objects – BLOBs- developed for SQL databases to store multimedia data) do not conveniently support content-based searches for multimedia content.
This is due to the relational database not being able to recognize the internal structure of a Binary Large Object and therefore internal multimedia data components cannot be retrieved…
Basically, a relational database is an "everything or nothing" structure- with files retrieved and stored as a whole, which makes a relational database completely inefficient for making multimedia data easily accessible to humans.

In order to effectively accommodate multimedia data, a database management system, such as an Object Oriented Database (OODB) or Object Relational Database Management System (ORDBMS).
Examples of Object Relational Database Management Systems include Odaptor (HP): UniSQL, ODB-II, and Illustra.
The flip-side of the coin, is that unlike non-multimedia data stored in relational databases, multimedia data cannot be easily indexed, retrieved or classified, except by way of social bookmarking and ranking-rating, by actual humans.

This is made possible by metadata retrieval methods, commonly referred to as tags, and tagging. This is why you can search for dogs, as an example, and a picture comes up based on your text search tem.
This is also referred to a schematic mode. Whereas doing a search with a picture of a dog to locate other dog pictures is referred to as paradigmatic mode.
However, metadata retrieval, search, and identify methods severely lack in being able to properly define uniform space and texture descriptions, such as the spatial relationships between 3D objects, etc.

The Content-Based Retrieval multimedia database search method (CBR), however, is specifically based on these types of searches. In other words, if you were to search an image or sub-image; you would then be shown other images or sub-images that related in some way to your the particular search, by way of color ratio or pattern, etc.

Monday, 1 June 2020

Fibre Channel


Fibre Channel is a set of standards for connecting storage devices in a fabric network. The Fibre Channel standard identifies a protocol and a collection of physical interfaces for managing computer peripheral components. This standard’s key purpose is managing large numbers of storage devices. Fibre Channel uses serial interfaces working at symbol rates from 133MB/s up to 4.25Gb/s. Optical as well as electrical signals are supported. Fibre Channel supports data transmission rates of 100MBps. It also allows 126 devices to be connected on a single network.
The channels are full duplex, offering full bandwidth and double the channel rate. Topologies comprise of point-to-point, shared loop, and switched. Fibre Channel is associated with numerous protocol layers, the most well-liked are the storage protocols SCSI (FCP) and ESCON (FICON). Fibre Channel is the primary technology used to deploy Storage Area Networks (SANs).


Fibre Channel Topologies

Fibre Channel supports three fabric topologies:
  • Fabric
  • Loop
  • Point-to-Point


Fibre Channel Physical Connectivity

Fibre Channel supports connectivity over fiber optic cabling or copper wiring.
Fibre Channel devices using fiber optic cabling use two unidirectional fiber optic cables for each connection. One fiber optic cable is used for transmitting, the other for receiving. Fibre channel over fiber optic cable supports cable distances of up to 10Km.
Fibre Channel devices that communicate over copper cabling are limited to distances of 30m.


Fibre Channel Devices

Fibre Channel Devices include:
  • Host Bust Adapters (HBA’s)
  • Fibre Channel Hubs
  • Fibre Channel Switches


Fibre Channel Ports

Fibre Channel uses a shorthand terminology to describe different types of connections to the Fibre Channel network.
Fibre Channel uses the term “ports” and defines seven different types of ports:
Short Name Descriptive Name Device Type Port Function
N-port Network Port Nodes Node port used to connect a node to a Fibre Channel switch
F-port Fabric Port Switches Switch port used to connect the Fibre Channel fabric to a node
L-port Loop Port Nodes Node port used to connect a node to a Fibre Channel loop
NL-port Network + Loop Port Nodes Node port that connects to both loops and switches
FL-port Fabric + Loop Port Switches Switch port that connects to both loops and switches
E-port Extender Port Switches Used to cascade Fibre Channel switches together
G-port General Port Switches General purpose port that can be configured to emulate other port types


Fibre Channel Standards

The American National Standards Institute (ANSI) defines the Fibre Channel standards.

FCAP (Fibre Channel Authentication Protocol)

FCAP is an optional authentication mechanism employed between any two devices or entities on a Fibre Channel network using certificates or optional keys.

FCPAP (Fibre Channel Password Authentication Protocol)

FCPAP is an optional password based authentication and key exchange protocol that is utilized in Fibre Channel Storage Area Networks (SANs).
FCPAP is used to mutually authenticate Fibre Channel ports to each other. This includes E_Ports, N_Ports, and Domain Controllers.

ESP over Fibre Channel

ESP (Encapsulating Security Payload) is an Internet standard for the authentication and encryption of IP packets. ESP is defined in RFC 2406: IP Encapsulating Security Payload (ESP).

FC-SP (Fibre Channel – Security Protocol)

Fibre Channel – Security Protocol (FC-SP) is a security protocol for Fibre Channel Protocol (FCP) and fiber connectivity (Ficon).
FC-SP is a project of Technical Committee T11 of the International Committee for Information Technology Standards (INCITS).
FC-SP is a security framework that includes protocols to enhance Fibre Channel security in several areas, including Fibre Channel device authentication, cryptographically secure key exchange, and cryptographically secure communication between Fibre Channel devices.
FC-SP is focused on protecting data in transit throughout the Fibre Channel network. FC-SP does not address the security of data that is stored on the Fibre Channel network.
ESP is widely deployed in IP networks and has been adapted for use in Fibre Channel networks. The IETF iSCSI proposal specifies ESP link authentication and optional encryption.
ESP over Fibre Channel is focused on protecting data in transit throughout the Fibre Channel network. ESP over Fibre Channel does not address the security of data that is stored on the Fibre Channel network.


SLAP (Switch Link Authentication Protocol)

SLAP is an authentication method for Fibre Channel switches that utilizes digital certificates to authenticate switch ports.
SLAP was designed to prevent the unauthorized addition of switches into a Fibre Channel network.

DH-CHAP

DH-CHAP (Diffie Hellman – Challenge Handshake Authentication Protocol) is a forthcoming Internet Standard for the authentication of devices connecting to a Fibre Channel switch.
DH-CHAP is a secure key-exchange authentication protocol that supports both switch-to-switch and host-to-switch authentication.
DH-CHAP supports MD5 and SHA-1 algorithm-based authentication.


Attacks against FCP

Attacks against FCP (Fibre Channel Protocol) include:
  • Node Name / Port Name spoofing at Port Login time
  • Source Port ID spoofing on data-less FCP commands
  • Snooping and spoofing on FC-AL
  • Snooping and Spoofing after Fabric reconfiguration
  • Denial of Service attacks can be made in User mode

Monday, 25 May 2020

SAN Zoning


SAN zoning is a method of arranging Fibre Channel devices into logical groups over the physical configuration of the fabric.
SAN zoning may be utilized to implement compartmentalization of data for security purposes.
Each device in a SAN may be placed into multiple zones.

Hard and Soft Zoning

Hard zoning is zoning which is implemented in hardware. Soft zoning is zoning which is implemented in software.
Hard zoning physically blocks access to a zone from any device outside of the zone.
Soft zoning uses filtering implemented in fibre channel switches to prevent ports from being seen from outside of their assigned zones. The security vulnerability in soft zoning is that the ports are still accessible if the user in another zone correctly guesses the fibre channel address.

WWN Zoning

WWN zoning uses name servers in the switches to either allow or block access to particular World Wide Names (WWNs) in the fabric.
A major advantage of WWN zoning is the ability to recable the fabric without having to redo the zone information.
WWN zoning is susceptible to unauthorized access, as the zone can be bypassed if an attacker is able to spoof the World Wide Name of an authorized HBA.

Port Zoning

Port zoning utilizes physical ports to define security zones. A users access to data is determined by what physical port he or she is connected to.
With port zoning, zone information must be updated every time a user changes switch ports. In addition, port zoning does not allow zones to overlap.
Port zoning is normally implemented using hard zoning, but could also be implemented using soft zoning.

Featured post

Top 10 Rare Windows Shortcuts to Supercharge Productivity

  Windows Key + X, U, U: This sequence quickly shuts down your computer. It's a great way to initiate a safe and swift shutdown without...